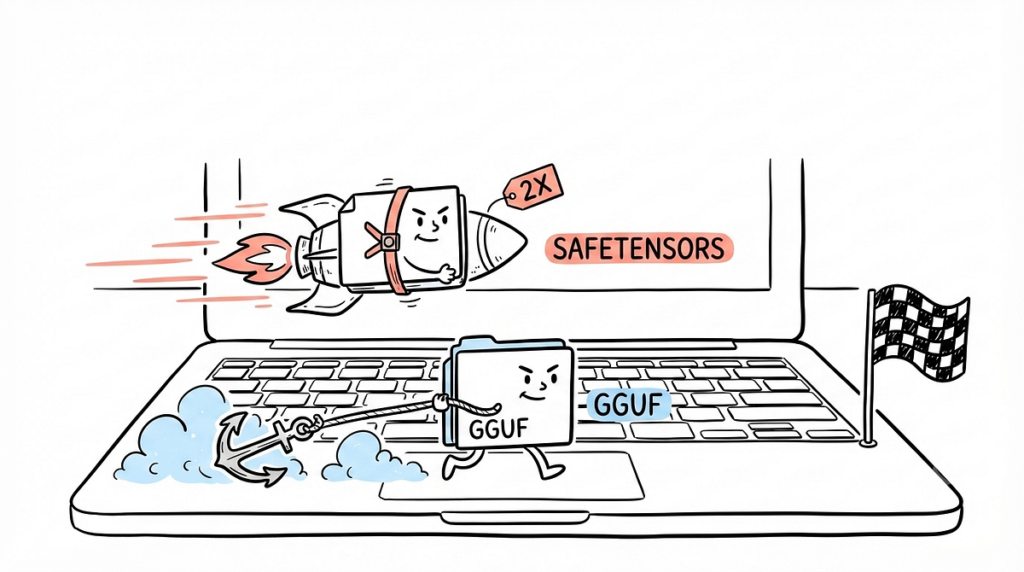
Ollama MLX Nearly Doubles LLM Speed on Your Mac: 58 to 112 tok/s, and Your Old Models Get None of It | by Kashif Mehmood | Jul, 2026
12 min read · 16 hours ago Press enter or click to view image in full size Ollama’s MLX engine
12 min read · 16 hours ago Press enter or click to view image in full size Ollama’s MLX engine
Healthcare data is among the most sensitive data there is. Sending it to a cloud AI service is often not
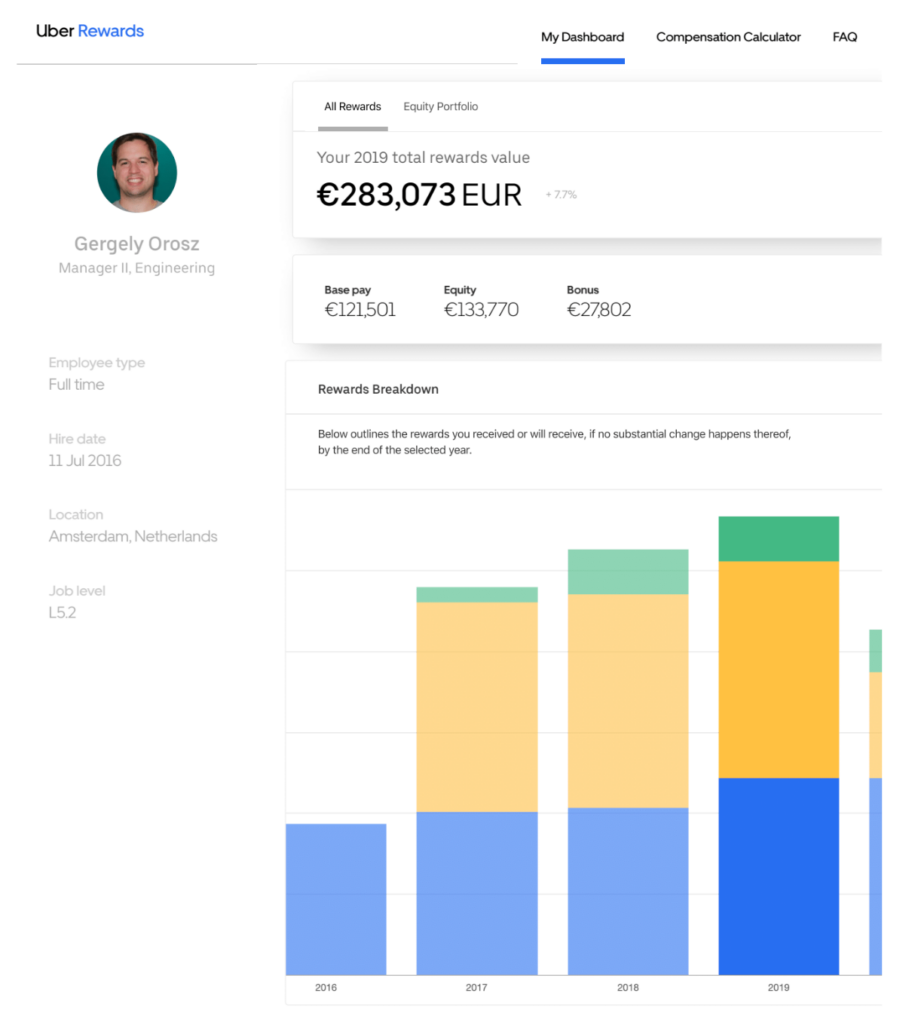
tl;dr: TechPays is joining Levels.fyi: so the leading tech salary site in Europe gets the love and care it deserves.
Q: Paging Charity! Our industry tends to espouse the value of collaboration, but then places on pedestals the worst models
Listen and watch now on YouTube, Spotify, and Apple. See the episode transcript at the top of this page, and
Agentic AI may be flipping the relationship between AI exposure and job posting growth. Key points: US software development job
A few months ago I wrote about what it means to stay gold — to hold on to the best parts
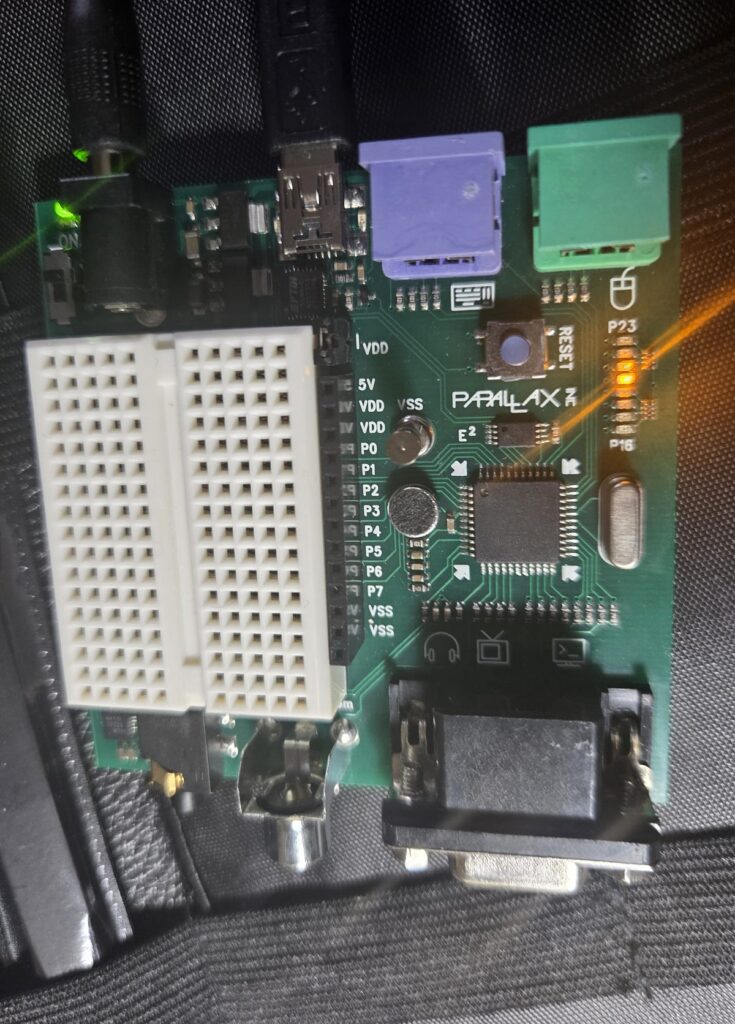
Using the linker map, worker-reported cog IDs, an LED runtime test, simulation and oscilloscope measurements By Maryclare Press enter or
Your network policy says: allow traffic from 10.0.1.45. Yesterday, 10.0.1.45 was your payment service. Today, after a rolling deployment, it’s
Hi, this is Gergely with a bonus, free issue of the Pragmatic Engineer Newsletter. In every issue, I cover Big